YOUR AI.
YOUR DATA.
YOUR RULES.
Your documents, conversations and knowledge shouldn't have to leave your device just to get intelligent answers.
The MX Silicon Stack puts powerful AI capabilities directly on your own hardware — giving you greater control over your data, models and workflows.
Every prompt, contract, or query is transmitted across public networks to remote server farms. Subject to corporate data retention, outage windows, and usage caps.
Models run on your Apple Silicon Mac or iPhone Neural Engine. Memory, documents, and inference loops execute entirely within your private application boundary.
What Happens to Your Data When You Ask AI a Question?
Cloud AI typically sends prompts and input data to a remote service for processing, where provider policies determine retention. Local AI processes prompts, documents, and inference directly on your hardware.
Cloud AI
Hosted Remote Infrastructure- Requires sending inference requests remotely:Your text, files, and attached images travel to cloud data centers.
- Subject to provider data-handling policies:Retention, compliance, and training exclusions depend on provider terms and configurations.
- Often requires an internet connection:Network dropouts, flight mode, or travel sever your access to the intelligence.
- May involve usage-based costs:Monthly token allowances, tiered subscription gates, and overage charges.
- Depends on external service availability:Server outages, high-traffic rate limits, and latency spikes disrupt workflows.
MX Local AI
Apple Silicon & Neural Engine- Runs compatible models on user hardware:Inference executes locally on GPU, CPU, and Apple Neural Engine.
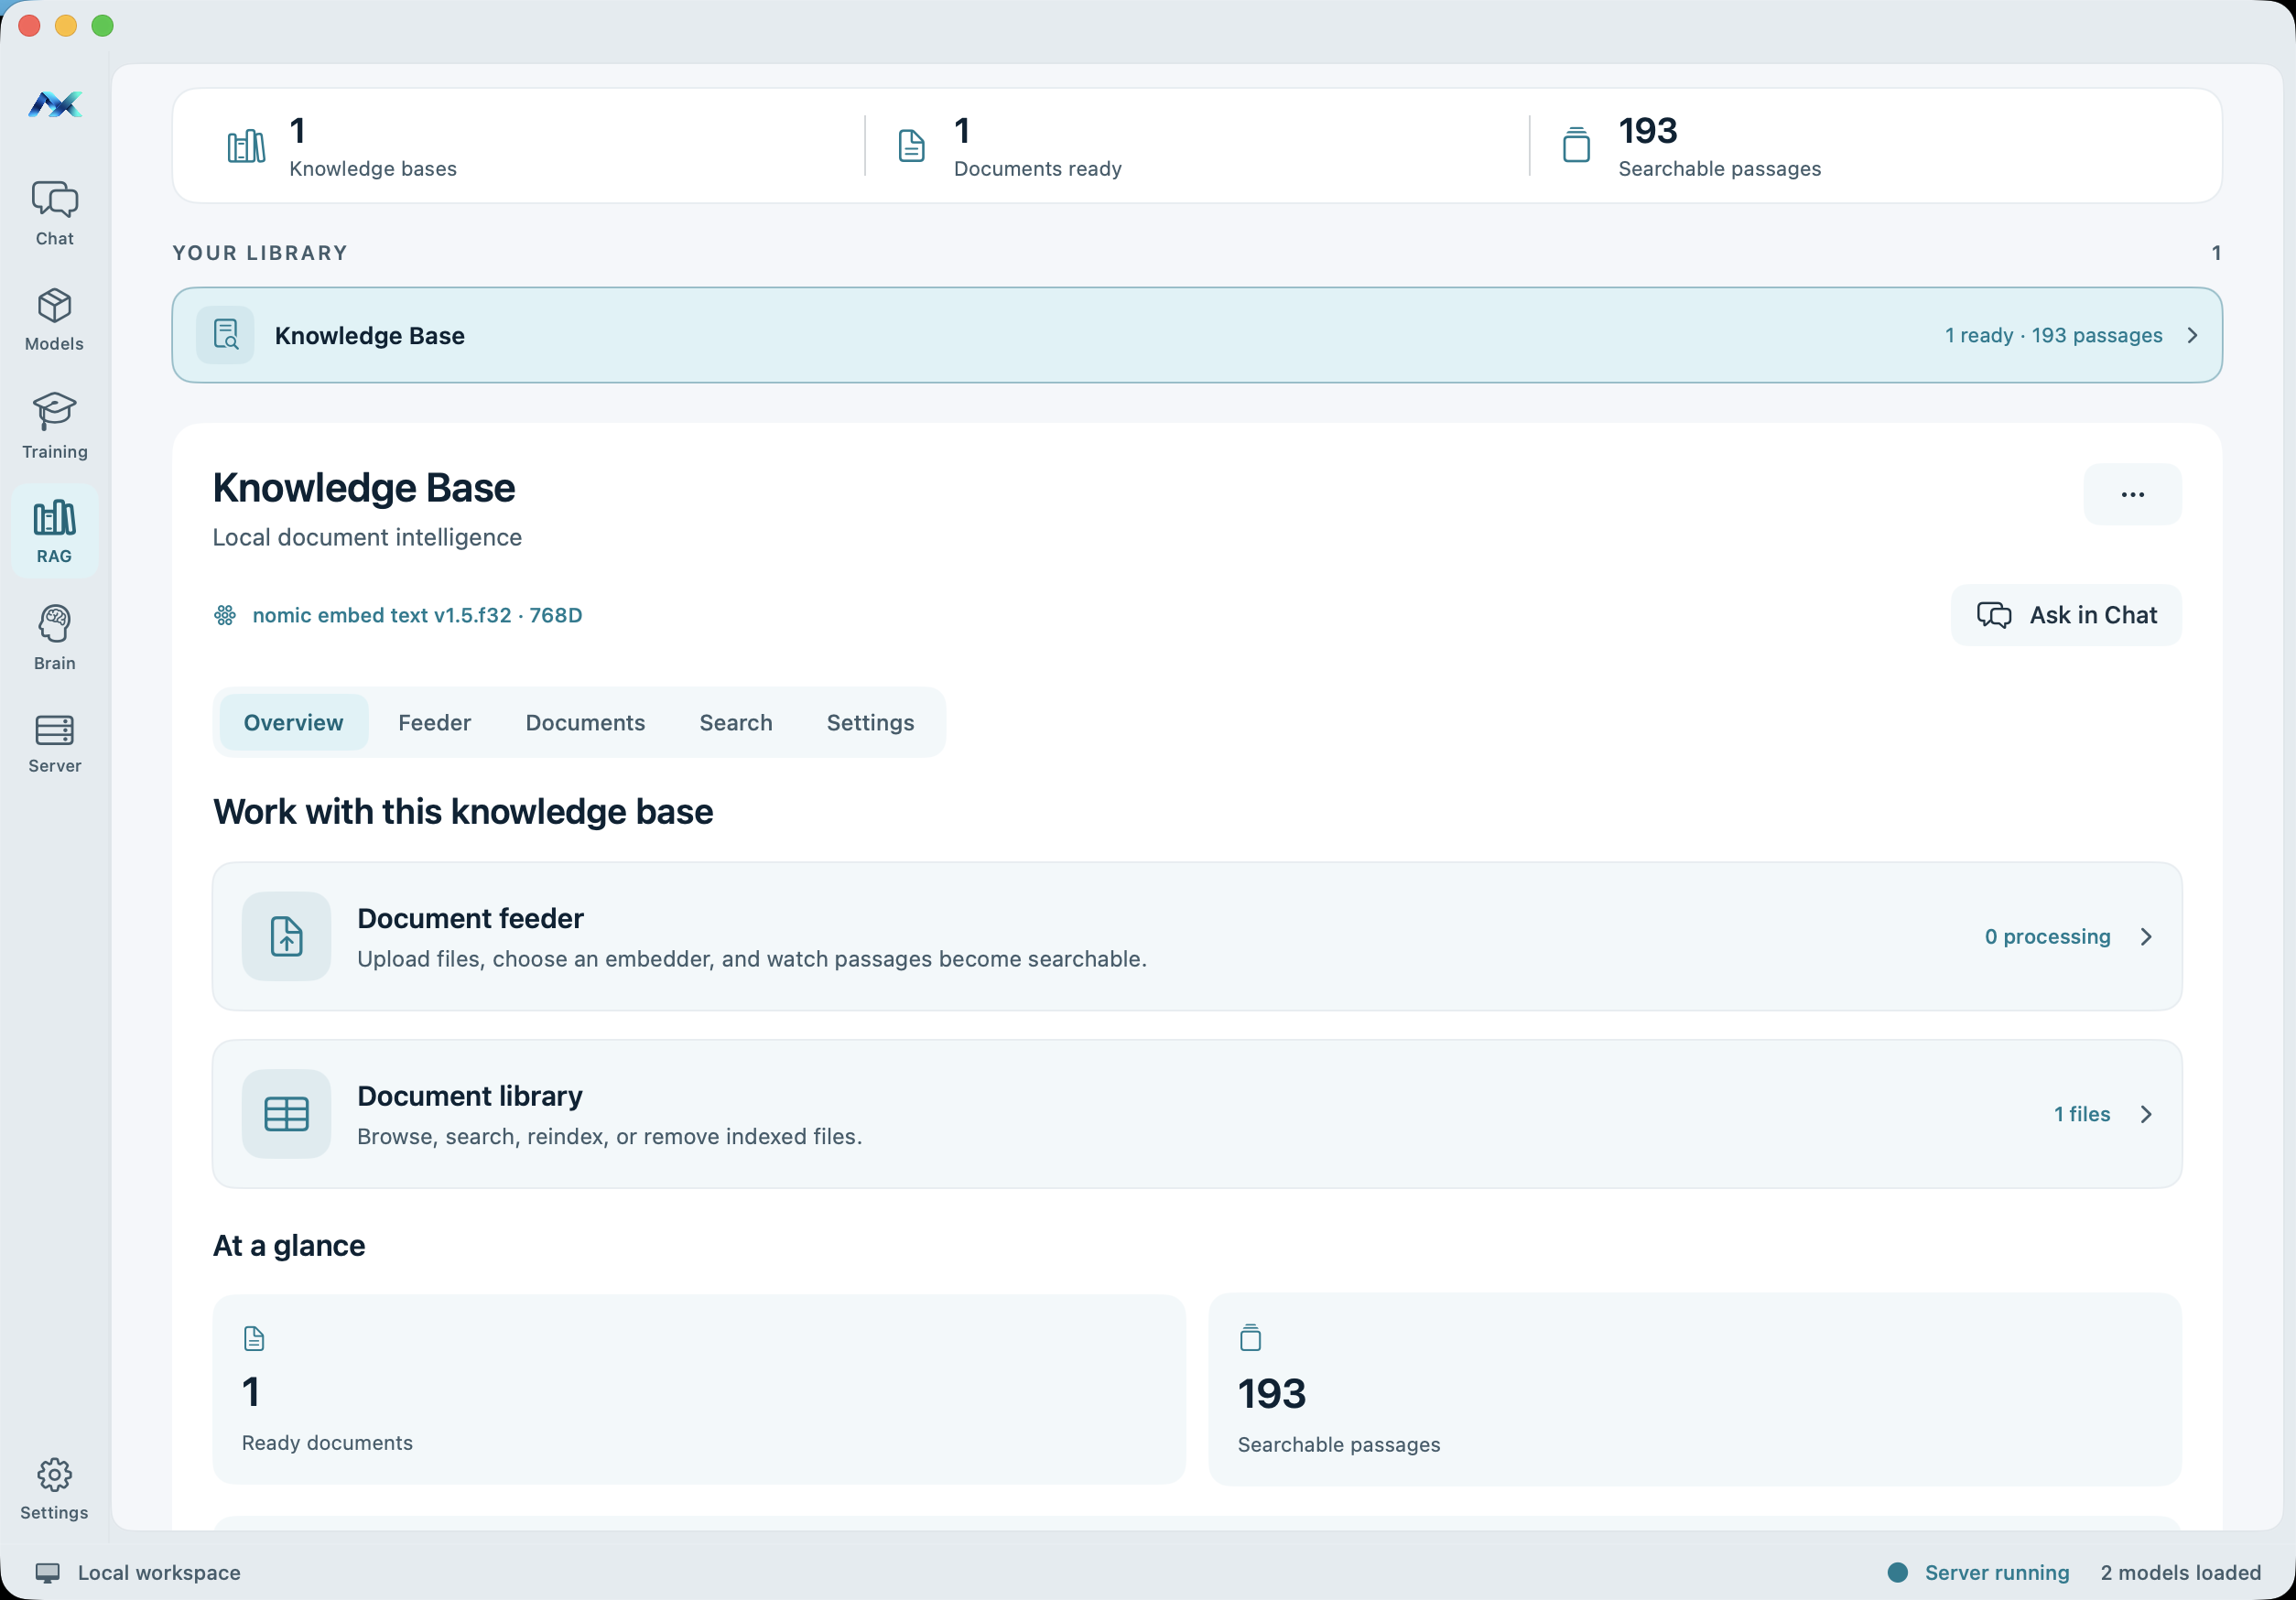
- Can process private documents locally:Embeddings, vector indexing, and RAG retrieval happen on-device without cloud upload.
- Operates without internet for supported workflows:Complete offline autonomy for chat, document lookup, memory recall, and offline libraries.
- Complete control over knowledge and memory:Local markdown vaults, human-readable preferences, and zero cloud profiling.
- No per-token cloud inference charges:Zero recurring API fees for fully local processing on the hardware you own.
Some Information Should Stay Close to Home.
Local AI significantly reduces the need to transmit high-value, confidential, or deeply personal content across third-party networks for inference.
Personal Documents
Private journals, personal correspondence, family records, and notes stay within your local sandbox rather than being scraped or logged.
Business Information
Internal strategy presentations, quarterly board materials, client deliverables, and confidential product roadmaps never touch cloud queues.
Legal Research
Sensitive case discovery, contractual clauses, litigation briefs, and attorney-client work products analyzed with complete isolation.
Health Information
Personal health logs, private reference libraries, and wellness tracking remain entirely on your iPhone or Mac without advertising profiling.
Research & Development
Unpublished algorithms, proprietary source code, patent drafts, and technical architectures kept strictly inside your internal perimeter.
Financial Information
Operating budgets, tax records, investment models, and payroll projections kept protected from third-party model retraining.
*Note: Local AI reduces external transmission. Brainstorm Labs does not claim regulatory certification (e.g. HIPAA/GDPR compliance) without independent validation by the user's compliance authority.
Keep More of Your AI Processing Inside Your Security Boundary.
By serving models locally and using native vector RAG indexing, MX Studio keeps sensitive enterprise documents flowing directly into the neural engine—eliminating unneeded third-party network hops.
External integrations, network-exposed endpoints, downloaded open weights, and third-party tools can introduce additional risks. Always verify model provenance, secure local ports with firewalls, and maintain system backups.
The Internet Goes Down.
Your AI Doesn't Have To.
When cables are severed, Wi-Fi fails in flight, or cell towers are out of reach, cloud assistants stop answering. The MX Silicon Stack keeps full conversational intelligence, document recall, and encyclopedic knowledge at your fingertips.
Stop Depending on Someone Else's Model Availability.
Cloud providers silently deprecate model versions, alter safety alignments, degrade reasoning benchmarks, or introduce new rate throttling. When you run locally, you determine what model runs and when it changes.
Complete Model Choice
Switch between Qwen, Llama, Mistral, Gemma, DeepSeek, or Flux image models. Pick the right balance of speed, parameter size, and reasoning depth for your exact task.
Permanent Version Retention
Downloaded GGUF and MLX weights remain on your SSD indefinitely. Your production prompts and agent workflows won't break because a cloud provider sunset a version.
Hardware-Tuned Quantization
Fit 27B models into 36GB unified memory using Q4_K_M or run unquantized FP16 weights on 96GB/128GB Mac Studio workstations with full GPU acceleration.
*Device compatibility varies with available unified memory and chip generation. Verify memory requirements prior to loading large models.
Your Hardware Is Already an AI Investment.
Modern Apple Silicon chips feature unified memory architectures and high-bandwidth Neural Engines. Instead of paying monthly token surcharges, unlock the workstation already sitting on your desk.
Cloud API Fees vs. Apple Silicon Local Inference
See how recurring per-token cloud bills compare to the hardware you already own.
- Bill scales with every query, agent loop, and RAG document pass
- Rate limits and surprise usage tier overages
- 0 per-token inference charges—run 1,000 queries or 1,000,000
- Estimated yearly savings: $1,333
Three Products. One Connected Local AI Experience.
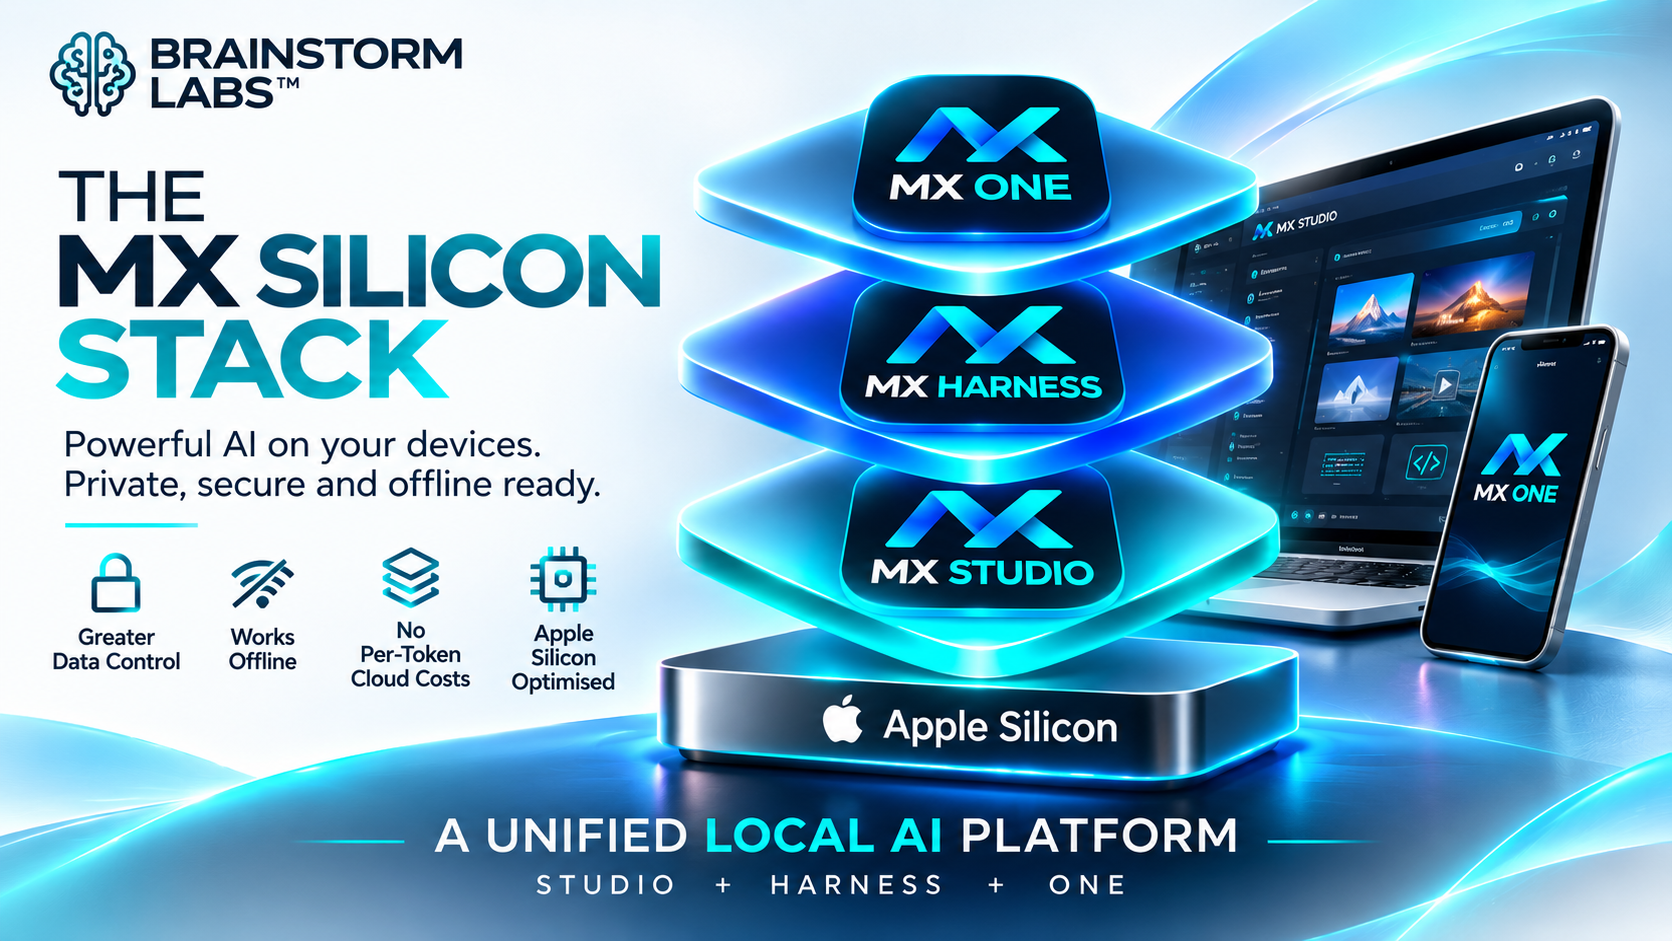
Brainstorm Labs architected the stack so you have the right local tool at every tier: the workstation engine on your Mac, an autonomous agent layer, and a mobile companion for your pocket.
MX Studio
Run high-parameter language models, generate local images and videos, index private RAG vaults, and serve an OpenAI-compatible API directly on macOS.
MX Harness
Turn local models into intelligent agents that use tools, execute sandboxed terminal tasks, orchestrate multi-agent workflows, and run custom presets.
MX ONE
Take offline AI, voice interaction, image vision, encrypted personal memory, and a 250k+ article encyclopedia anywhere your iPhone goes.
THE COMPLETE GUIDE TO PRIVATE & LOCAL AI
Everything you need to know about running open-weight models, local RAG architecture, hardware optimization, and data sovereignty on Apple Silicon.
Discover what your hardware can really do with AI. This guide covers local models, private knowledge bases, intelligent agents and offline AI — tailored to the MX product you're most interested in.
Get Your Free Starter Kit
Delivered to your email when our system confirms your request
POWERFUL AI.
PRIVATE BY DESIGN.
BUILT FOR YOUR HARDWARE.
Discover what happens when intelligence runs on your own devices, your documents remain under your control and your AI works on your terms.